
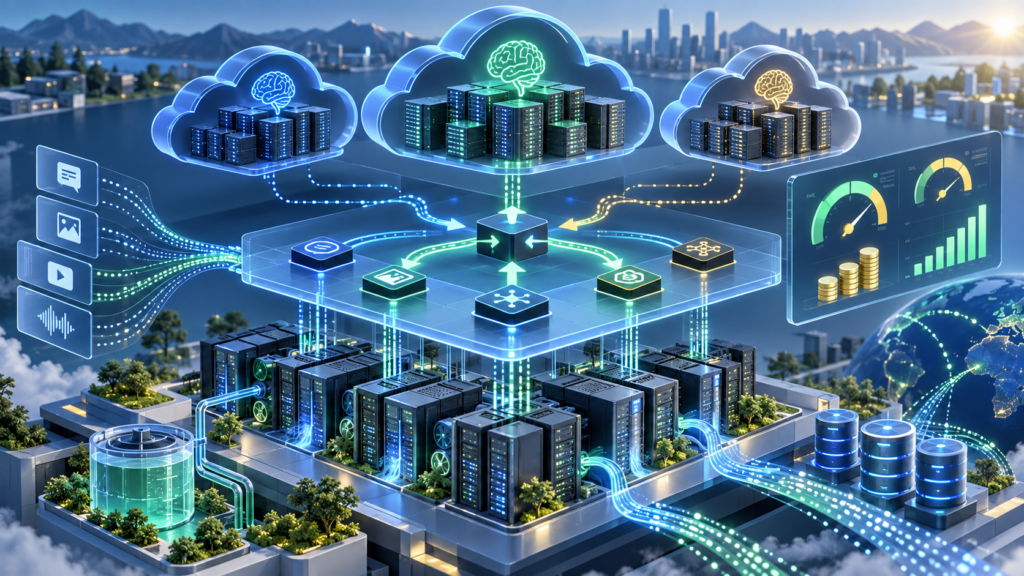
AI applications often begin with a simple cost assumption: multiply the model price by the expected number of requests. In production, the real bill also includes storage, retrieval, bandwidth, observability, background jobs, GPU or CPU capacity, and idle resources. Cost optimization should therefore begin during architecture design.
Choose the right model for each task
Not every request needs the most capable model. Use smaller or specialized models for classification, extraction, routing, and summarization, and reserve larger models for complex reasoning. A routing layer can choose the model based on task difficulty, confidence, and business impact.
Reduce unnecessary inference
Cache stable answers and repeated retrieval results. Deduplicate documents before indexing them. Use deterministic processing for tasks that do not require generation. Batch background work where latency is not critical, and set sensible limits on context size and output length.
Design infrastructure around workload patterns
Interactive requests and batch workloads have different infrastructure needs. Autoscale user-facing services for demand, schedule non-urgent processing during efficient periods, and shut down development resources when they are not being used. Keep environments separate so testing does not accidentally consume production-scale capacity.
Make costs visible
Track cost by product, team, customer, model, environment, and workflow. Record tokens, latency, cache hits, retrieval volume, and tool usage. A single monthly cloud bill is not enough to identify which feature is creating the expense.
Balance performance and cost
The cheapest design is not always the best design. Slow responses can reduce conversion and employee adoption, while excessive retries can cost more than a faster first attempt. Define service targets for latency, accuracy, availability, and cost per successful task, then optimize against all four.
A practical cost review
- Establish a baseline from real or representative traffic.
- Separate fixed infrastructure costs from per-request costs.
- Measure model and retrieval usage independently.
- Introduce caching, routing, and autoscaling one change at a time.
- Review the results monthly and update budgets as usage changes.
Cloud cost optimization is not about cutting capacity blindly. It is about matching infrastructure and model choices to the value of each workflow. Teams that build this visibility early can scale AI applications with more confidence and fewer billing surprises.
Put these ideas into practice
Explore where AI could help your business.
Discuss your workflow, available data, and the result you want before deciding what to build.